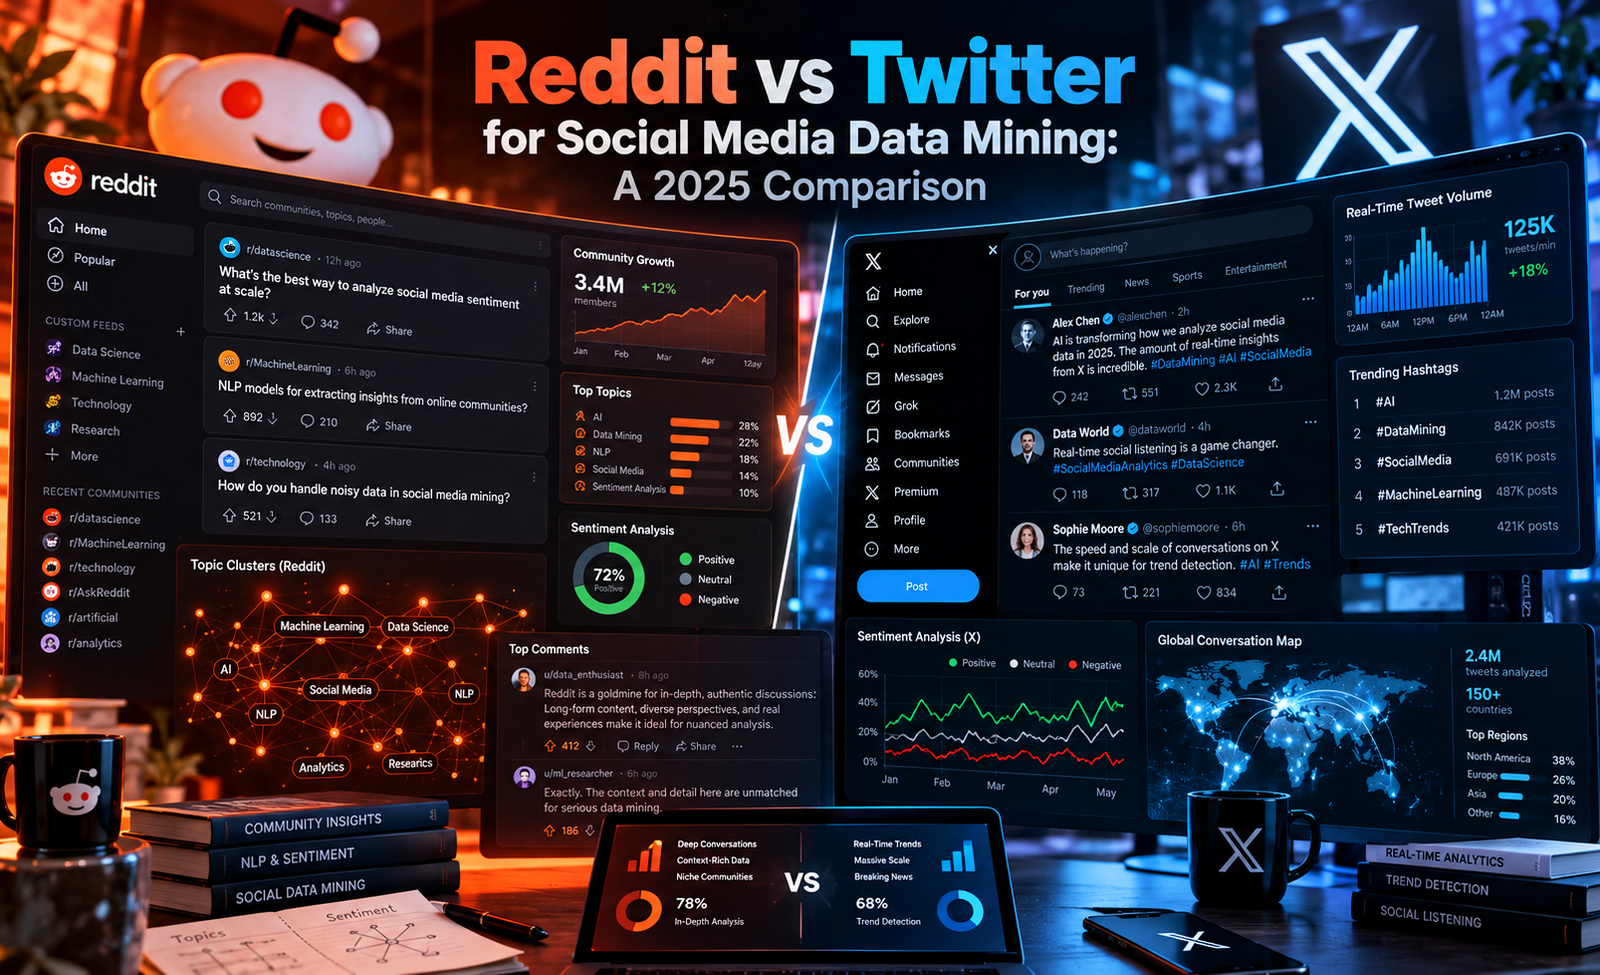
Social media data mining has never been more useful — or more complicated. Both Reddit and Twitter (now rebranded as X) sit at the top of most researchers’ and marketers’ shortlists when it comes to extracting public conversation data. But after a turbulent couple of years for both platforms’ developer ecosystems, the landscape looks very different in 2025 than it did even two years ago.
This comparison covers what each platform actually offers for data collection purposes today: the data types available, the access methods and their real costs, the quality of signal you get, and which platform fits which use case. If you’re deciding where to focus your data mining efforts — or whether to use both — this is the practical breakdown you need.
How Both Platforms Changed in 2023
It’s impossible to compare Reddit and Twitter as data sources without addressing what happened to both of them in the same twelve-month window.
Twitter/X under Elon Musk began aggressively monetizing API access in early 2023. The free API tier, which had allowed researchers and developers to collect tweets at no cost, was eliminated. Basic access was set at $100/month for 10,000 tweets per month. The Pro tier costs $5,000/month. Enterprise pricing is negotiated separately and runs into six figures annually for high-volume access. The change effectively ended large-scale Twitter data collection for anyone without a substantial budget.
Reddit followed a few months later with its own API restructuring, ending free large-scale access and introducing commercial licensing requirements for high-volume or commercial use. The free tier remained for low-volume personal use (100 queries per minute), but anything beyond that requires a paid agreement.
Both moves were driven by the same logic: platforms want to monetize the data that AI companies and researchers have been using for free. The practical effect for data miners is that neither platform is the “free firehose” it once was. Costs now factor heavily into platform selection — and in 2025, the cost gap between Reddit and Twitter data access is significant.
Data Types: What Each Platform Offers
Reddit’s public data is structured around four entity types: posts, comments, users, and subreddits (communities). Each has a rich set of associated fields.
A Reddit post includes its title, full body text, score, upvote ratio, comment count, flair, media attachments, and permalink. Comments include the full text, score, author, timestamp, reply count, and a stable permalink for thread reconstruction. User profiles expose post karma, comment karma, account age, bio, and moderation flags. Subreddits provide subscriber counts, rules, moderator lists, descriptions, and growth metadata.
What makes Reddit data particularly valuable for mining is depth. Reddit discussions are threaded and often long — a single post can have thousands of comments spanning multiple days, with nested replies that constitute genuine back-and-forth debate. This makes Reddit data rich for NLP tasks, sentiment analysis, and qualitative research in a way that short-form content rarely is.
Twitter/X
Twitter’s data is centered on tweets: short posts of up to 280 characters (or longer for paying subscribers), retweets, quote tweets, replies, and associated engagement metrics (likes, retweets, impressions). User profiles include follower/following counts, verified status, location (when provided), and account creation date.
Twitter’s data is valuable for its breadth and speed. A breaking news event, a product launch, or a cultural moment hits Twitter before almost any other platform and spreads rapidly. The public nature of most accounts means you get a wide cross-section of opinion quickly. Hashtags and trending topics make topical aggregation straightforward.
The trade-off is depth: most tweets are short, context-free, and often reactive rather than substantive. Mining Twitter for nuanced consumer opinion requires large volumes to compensate for the low information density per post.
Access Methods and Real Costs in 2025
Official API: The free tier allows 100 queries per minute via OAuth, suitable for small personal projects. Commercial use requires a paid data license, negotiated directly with Reddit. Pricing is based on volume and use case.
Dedicated Reddit scrapers: A managed reddit scraper like RedScraper operates on a compute-time billing model — you pay for successful data runs rather than per API call. A single run can return up to 10,000 records across posts, comments, users, or subreddits. This model is significantly more cost-effective for batch analytical workloads than the per-call API pricing. No-code dashboard access means non-technical team members can run their own collection tasks without engineering support.
Twitter/X
Official API: Free tier no longer exists for practical data collection. The Basic tier costs $100/month for 10,000 tweets. Pro is $5,000/month for 1,000,000 tweets. Enterprise pricing is negotiated for higher volumes. Read access and write access are priced separately.
Third-party Twitter scrapers: Several tools exist that collect Twitter data without using the official API. These operate in a legal grey area since Twitter’s terms of service prohibit scraping, and Twitter has actively sent cease-and-desist letters to scraper providers. Reliability is variable, and the risk of tool discontinuation is real.
Cost comparison in practice: For a team collecting 50,000 records per month, Reddit data via a managed scraper will cost a fraction of what equivalent Twitter data costs through the official API. The gap is large enough to be a deciding factor for budget-constrained teams.
Data Quality and Signal Type
This is where the two platforms diverge most meaningfully — and where the right answer depends entirely on what you’re trying to learn.
Reddit signal: depth, specificity, niche expertise
Reddit is organized into subreddits — topic-specific communities that self-select for interest and expertise. When someone posts in r/personalfinance, r/MachineLearning, or r/diabetes, they’re writing to an audience that shares their context. This produces discussions that are substantive, specific, and often expert-level in niche domains.
For a company researching customer pain points around a software product, the relevant subreddits will contain detailed, unprompted accounts of real user experiences — frustrations, workarounds, comparisons with competitors — written by people who chose to engage with that topic specifically. The signal-to-noise ratio for subject-specific research is high.
Reddit data is also relatively stable over time. Posts and comment threads persist and remain searchable for years. A 2021 discussion about a product issue is still there in 2025, still contributing to a dataset.
Twitter signal: speed, breadth, cultural pulse
Twitter data captures the moment. During a product launch, a PR crisis, or a news event, Twitter aggregates public reaction faster than any other platform. If you need to understand immediate public sentiment — how people feel about something in the first 24 hours — Twitter is the right source.
Twitter also provides a broader demographic cross-section than Reddit. While Reddit skews toward specific interest communities, Twitter’s public conversation includes casual observers, journalists, executives, and cultural figures in the same stream. For brand monitoring and PR response, this breadth has genuine value.
The weakness is that Twitter posts are short, often decontextualized, and frequently reactive rather than considered. High-volume collection compensates somewhat, but the per-post information density is much lower than Reddit.
Use Case Comparison
Market research and consumer insights
Reddit wins. Subreddits like r/BuyItForLife, r/personalfinance, r/femalefashionadvice, and thousands of product-specific communities contain detailed, unprompted consumer opinion written by engaged, self-selected audiences. Collecting this data with a reddit data extractor gives you a structured dataset of real consumer language around any product category.
Twitter can supplement this with volume data — how many people are mentioning a brand — but rarely provides the qualitative depth that informs actual product decisions.
Real-time brand monitoring
Twitter wins. If a story breaks about your brand, it hits Twitter first and spreads fast. For PR teams that need to monitor and respond to developing situations in real time, Twitter’s speed advantage is decisive.
Reddit brand mentions tend to appear in more deliberate, considered posts — useful for understanding sustained perception, less useful for catching a fast-moving story.
Academic and NLP research
Reddit wins for text quality; Twitter wins for volume and diversity.
Reddit’s long-form comments and threaded discussions make it a better source for training language models on coherent, contextual text. The content is longer, better structured, and typically more substantive. For tasks like sentiment classification, topic modeling, or discourse analysis, Reddit produces richer training data per record.
Twitter’s advantage is the sheer volume of data and its linguistic diversity — many languages, many registers, many demographic groups. For research requiring broad coverage rather than depth, Twitter data (when accessible) has historically been the default.
Competitive intelligence
Reddit wins on depth; use both for full coverage.
Reddit surfaces detailed competitor comparisons, user complaints, and feature requests in a way that Twitter doesn’t — because Reddit users write in full paragraphs and engage in multi-turn discussions. Monitoring subreddits relevant to your industry gives you a sustained, deep view of competitive positioning from the user perspective.
Twitter adds volume signals: how much is a competitor being talked about, and in what tone? Combining both gives the most complete picture.
Political and social research
Twitter has historically been the standard; Reddit is a stronger alternative in 2025.
Academic social media research was long built on Twitter’s Decahose and Academic Research API, both of which are now prohibitively expensive or discontinued. Reddit’s community structure and long-form content make it a viable and increasingly mainstream alternative for studying public opinion, discourse dynamics, and information spread.
Practical Considerations for 2025
Legal and terms of service: Reddit permits non-commercial data access under its terms and has a defined data API program for commercial use. Twitter/X explicitly prohibits scraping and has taken legal action against scraper operators. For teams that need data access to be clearly above-board, Reddit is the lower-risk platform.
Data persistence: Reddit posts and comments persist indefinitely (unless deleted by the user or moderators). Twitter’s API only allows access to recent tweets by default — historical data requires expensive Academic Research access, which is now only available to credentialed institutions at high cost. For longitudinal research, Reddit’s persistence is a meaningful advantage.
Anonymity and demographic data: Reddit users are typically pseudonymous and don’t provide verified demographic information. Twitter/X users also vary widely in how much identifying information they share, but verified accounts and professional profiles provide richer metadata in some cases. Neither platform is reliable for demographic inference without additional methods.
Volume and scale: Twitter generates more posts per day than Reddit by a significant margin. For use cases requiring very high volume across a general population — not a specific topic or community — Twitter’s scale has historically been the advantage. But access to that scale now costs thousands of dollars per month.
Which Platform Should You Prioritize?
There’s no universal answer, but here’s a practical framework:
Start with Reddit if: your research is topic or community-specific; you need qualitative depth over volume; you’re working with a limited budget; you want data in structured CSV or Excel format ready for analysis; or you need data that will still be accessible and affordable six months from now.
Add Twitter if: real-time monitoring is critical; you’re tracking broad cultural or news-driven events; you have budget for API access or an existing Twitter data relationship; or your research specifically requires Twitter’s user base.
For most analytical workloads — market research, competitive intelligence, academic study, customer insight — Reddit delivers more usable signal per dollar in 2025 than Twitter does. The platform’s community structure, content depth, and more accessible data ecosystem make it the pragmatic starting point for teams building a social data practice.
RedScraper collects Reddit posts, comments, users, and subreddits through a no-code dashboard or API, with export to CSV, JSON, Excel, and XML. Start collecting Reddit data here.